End-to-End AI Cluster Setup and Deployment

From Bare Metal to a Production-Ready Cluster

We design and deploy fully redundant AI clusters as unified, production-ready systems, covering compute, storage, networking, orchestration, and performance optimization.

Capabilities

What We Offer

Physical Installation

We perform precision rack installation covering compute, storage, head nodes, and redundant switches, while fully managing labeling, airflow, and power planning.

Cabling and Optical Components

We design port-mapped cabling across all networks and ensure validated transceiver selection based on bandwidth, latency, and topology requirements.

Network Infrastructure

We design and configure redundant leaf-spine or MLAG network architectures, enable InfiniBand or RoCE support, optimize MTU settings, and perform RDMA validation.

Firmware and Drivers

We establish a unified firmware and operating system standard across all components and configure a validated driver stack compatible with GPUs, networking, and storage.

Cluster Management

We deploy NVIDIA Base Command Manager (BCM) and centralized cluster management platforms, centrally managing access, provisioning, monitoring, and high-availability processes.

Orchestration and Scheduling

We deploy production-ready clusters based on Kubernetes, OpenShift, or Slurm with Run:ai integration, enabling efficient workload scheduling and GPU optimization.

Based on Architectural Plans

Architectural Integrity

SCALABLE DESIGN INSPIRED BY NVIDIA BASEPOD AND SUPERPOD REFERENCE ARCHITECTURES.

We don’t build clusters by simply assembling individual components. We design them using a blueprint-driven architectural model inspired by proven BasePOD and SuperPOD principles.

Every deployment follows a layered and validated framework in which compute, high-speed networking, storage, and the control plane are designed as a unified system rather than as independent components.

This approach eliminates architectural bottlenecks before they arise and ensures predictable scalability from day one.
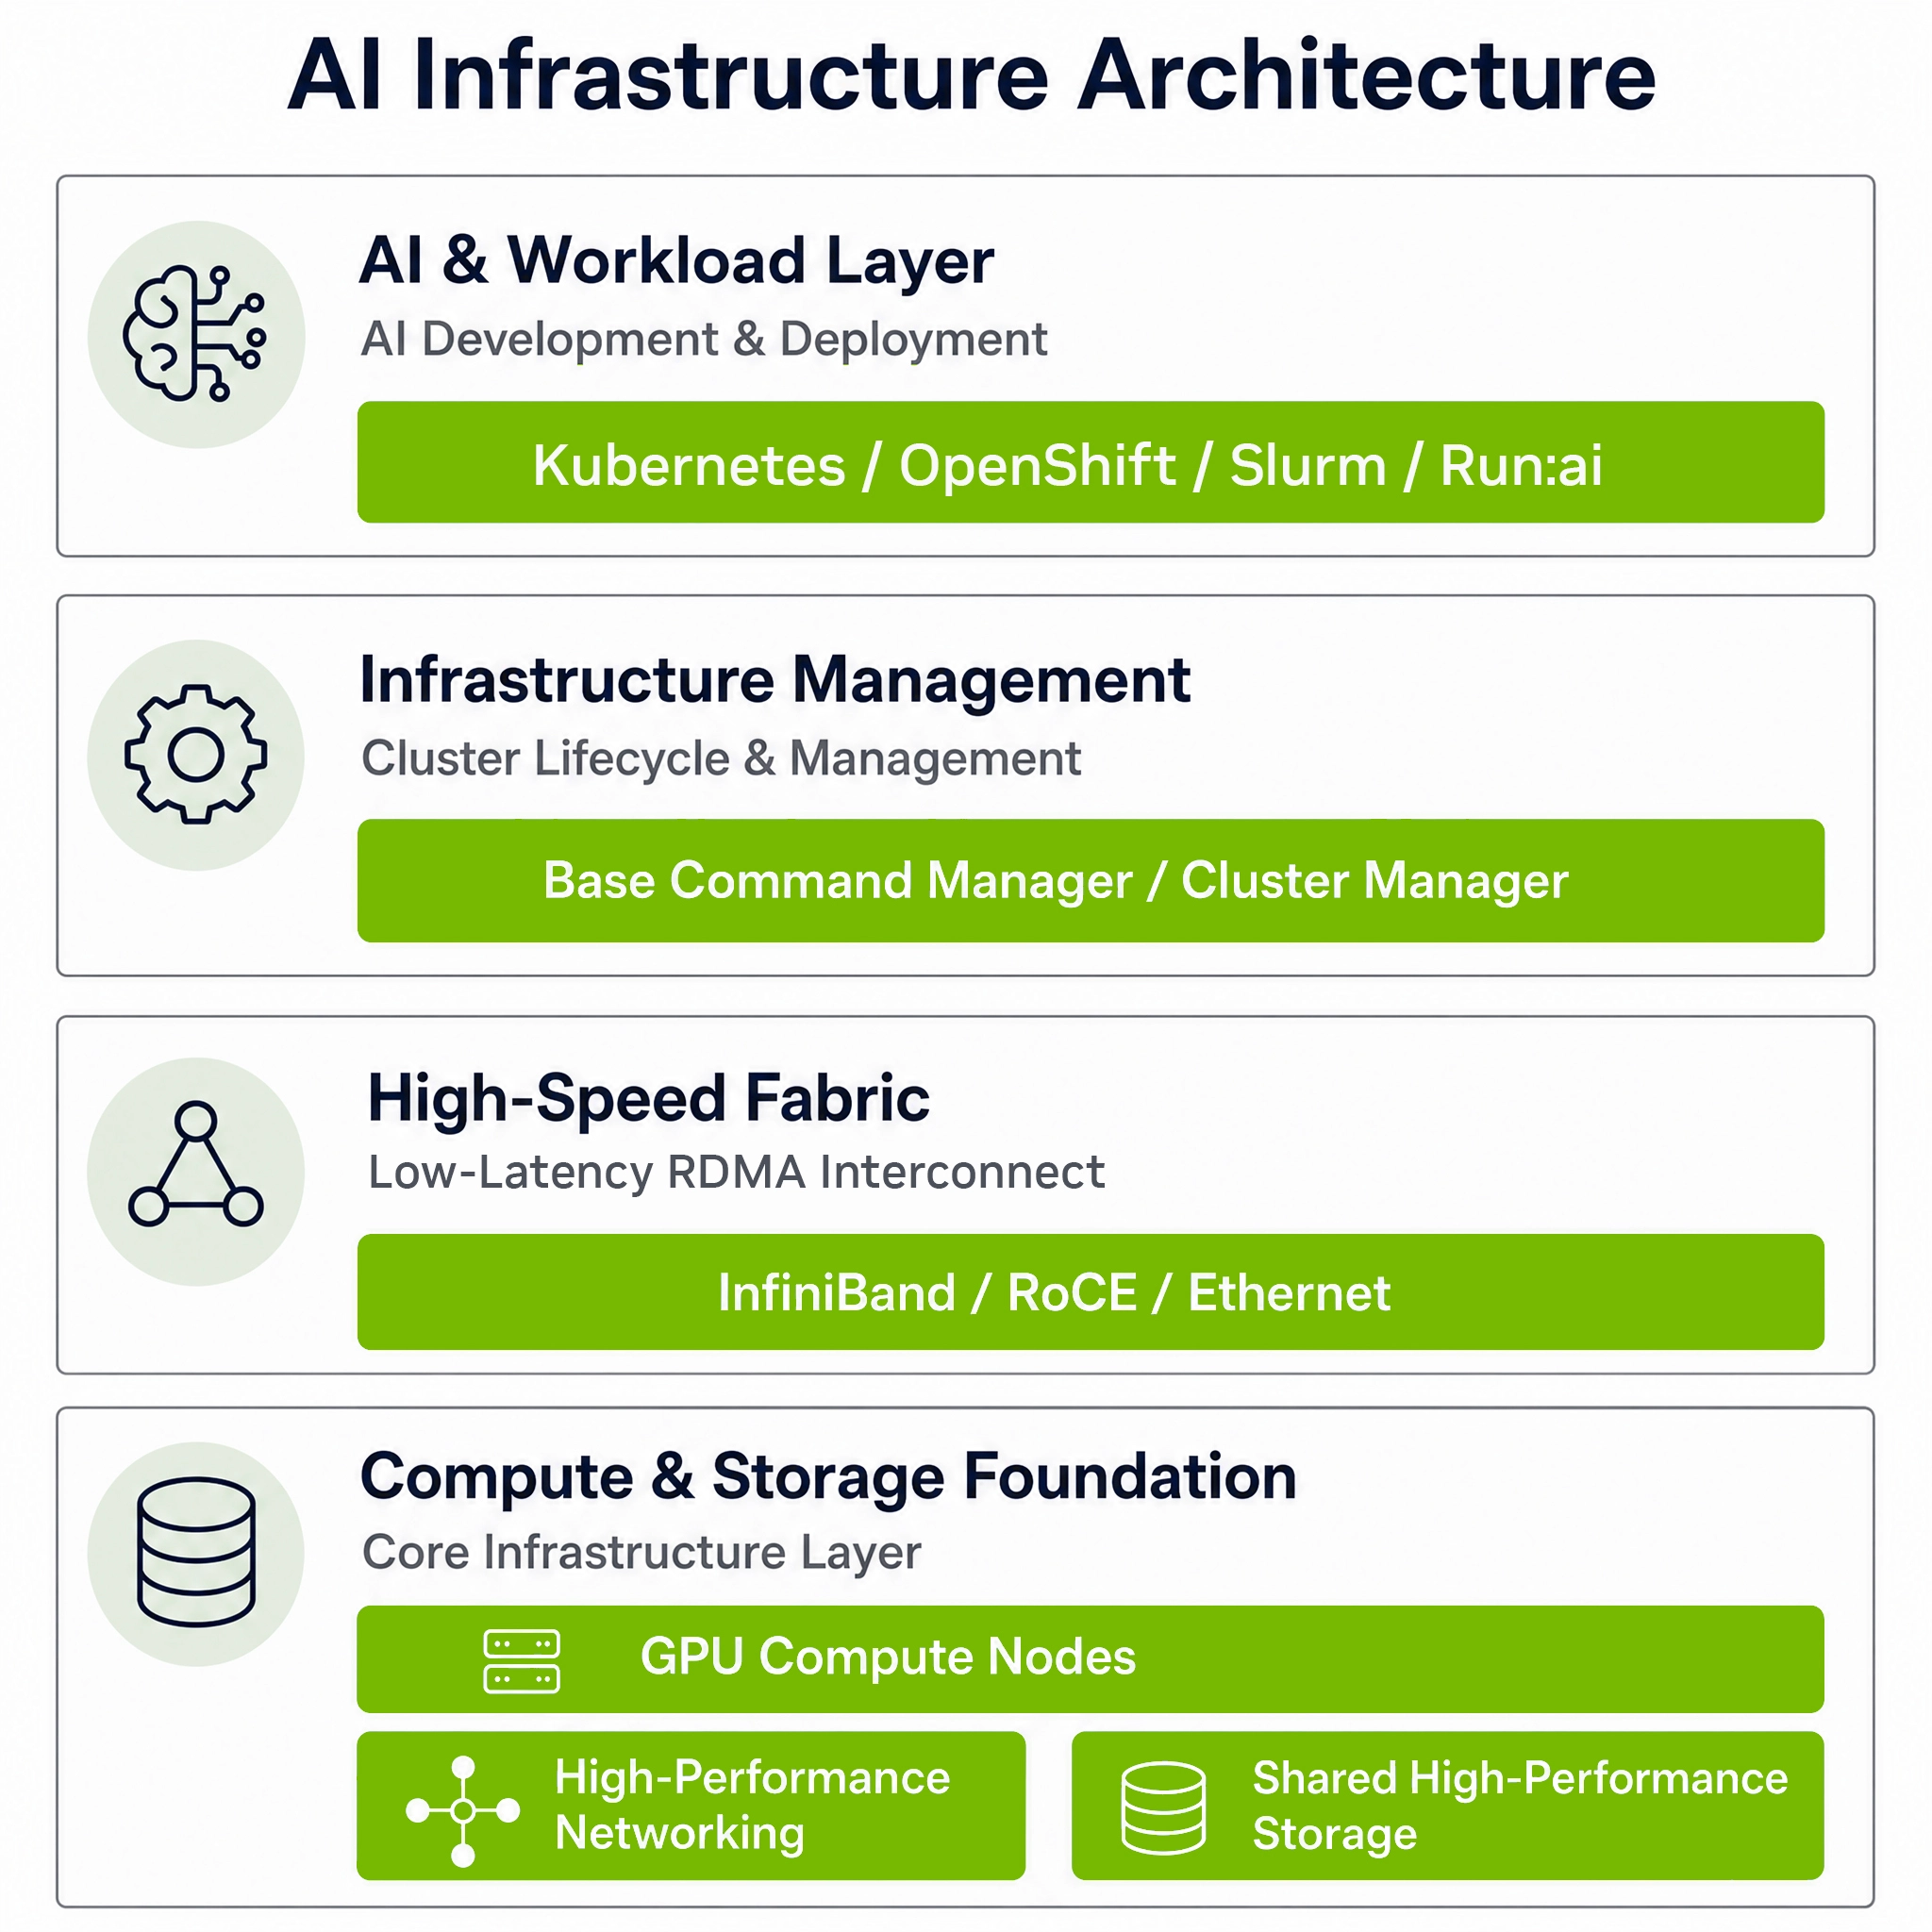
Infrastructure Platform
Enterprise Deployment Architecture

Deployment Packages

Structured engagement models tailored to cluster scale, performance requirements, and operational maturity.

FOUNDATION

Single Rack

Proof of Concept (PoC) and Small AI Pods


✔ Single-rack or small pod deployment
✔ Kubernetes or Slurm deployment
✔ Basic monitoring and health validation
✔ Standard Ethernet networking
✔ Initial workload validation

SCALING

Multi-Rack

Growing AI Infrastructure and Multi-Rack Expansion


✔ Multi-rack architecture design
✔ InfiniBand or RoCE network infrastructure optimization
✔ Shared or parallel storage integration
✔ Run:ai deployment and GPU allocation policies
✔ Performance validation and optimization

ENTERPRISE

Critical Workloads

Production-Grade AI Factories and Mission-Critical Environments


✔ High-availability control plane
✔ Dual network infrastructure and redundancy validation
✔ Air-gapped deployment processes
✔ Disaster recovery planning and failover validation
✔ Operational runbook and knowledge transfer
Let’s Design Your Infrastructure Together

Our solution architects are ready to review your requirements. Share your technical specifications below so we can prepare a tailored deployment proposal for you.

    End-to-End AI Cluster Setup and Deployment

    From Bare Metal to a Production-Ready Cluster

    We design and deploy fully redundant AI clusters as unified, production-ready systems, covering compute, storage, networking, orchestration, and performance optimization.

    Capabilities

    What We Offer

    Physical Installation

    We perform precision rack installation covering compute, storage, head nodes, and redundant switches, while fully managing labeling, airflow, and power planning.

    Cabling and Optical Components

    We design port-mapped cabling across all networks and ensure validated transceiver selection based on bandwidth, latency, and topology requirements.

    Network Infrastructure

    We design and configure redundant leaf-spine or MLAG network architectures, enable InfiniBand or RoCE support, optimize MTU settings, and perform RDMA validation.

    Firmware and Drivers

    We establish a unified firmware and operating system standard across all components and configure a validated driver stack compatible with GPUs, networking, and storage.

    Cluster Management

    We deploy NVIDIA Base Command Manager (BCM) and centralized cluster management platforms, centrally managing access, provisioning, monitoring, and high-availability processes.

    Orchestration and Scheduling

    We deploy production-ready clusters based on Kubernetes, OpenShift, or Slurm with Run:ai integration, enabling workload scheduling and GPU optimization.

    Based on Architectural Plans

    Architectural Integrity

    SCALABLE DESIGN INSPIRED BY NVIDIA BASEPOD AND SUPERPOD REFERENCE ARCHITECTURES.

    We don’t build clusters by simply assembling individual components. We design them using a blueprint-driven architectural model inspired by proven BasePOD and SuperPOD principles.

    Every deployment follows a layered and validated framework in which compute, high-speed networking, storage, and the control plane are designed as a unified system rather than as independent components.

    This approach eliminates architectural bottlenecks before they arise and ensures predictable scalability from day one.

    Deployment Packages

    Structured engagement models tailored to cluster scale, performance requirements, and operational maturity.

    FOUNDATION

    Single Rack

    Proof of Concept (PoC) and Small AI Pods


    ✔ Single-rack or small pod deployment
    ✔ Kubernetes or Slurm deployment
    ✔ Basic monitoring and health validation
    ✔ Standard Ethernet networking
    ✔ Initial workload validation

    SCALING

    Multi-Rack

    Growing AI Infrastructure and Multi-Rack Expansion


    ✔ Multi-rack architecture design
    ✔ InfiniBand or RoCE network infrastructure optimization
    ✔ Shared or parallel storage integration
    ✔ Run:ai deployment and GPU allocation policies
    ✔ Performance validation and optimization

    ENTERPRISE

    Critical Workloads

    Production-Grade AI Factories and Mission-Critical Environments


    ✔ High-availability control plane
    ✔ Dual network infrastructure and redundancy validation
    ✔ Air-gapped deployment processes
    ✔ Disaster recovery planning and failover validation
    ✔ Operational runbook and knowledge transfer

    Let’s Design Your Infrastructure Together

    Our solution architects are ready to review your requirements. Share your technical specifications below so we can prepare a tailored deployment proposal for you.